17 / 25
Claude Opus 5.5 leads all six models with a mean rank score of 91.2.
† Project Leader * Corresponding Authors
17 / 25
Claude Opus 5.5 leads all six models with a mean rank score of 91.2.
| # | Model | Rank score | 95% CI | Wins | First valid score | Visible output tokens |
|---|
Rank the six models by each task’s best valid within-budget score, then average 100 × (6 − rank) / 5 equally across tasks. Exact ties share average rank; a run without a valid scored submission receives zero. The 95% task-bootstrap confidence intervals use 10,000 resamples for the full suite and 3,000 for filtered groups.
Visible tokens use o200k_base for agent text and tool-call content, excluding tool responses, repeated code-diff displays, and hidden reasoning. Full-suite totals aggregate all 25 tasks. First-score time is the median across scored runs in the selected tasks.
Click a task below to view its details.
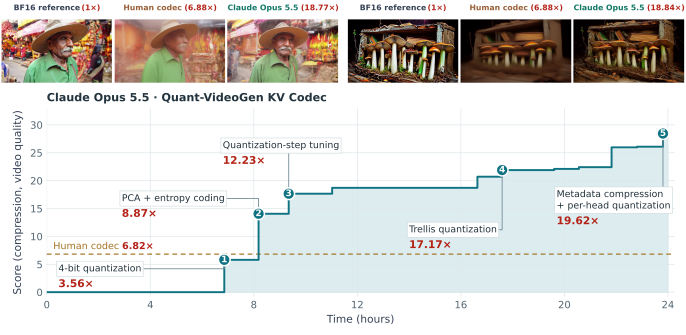
6.82× → 19.86×
Claude designs a new compression method that increases the compression ratio from the human codec’s 6.82× to 19.86×, while improving video quality.
9 / 12
Longer horizons are more effective for module and system tasks, while short-horizon TTS (test-time scaling) remains competitive on operators.
Loading optimization trajectories…


Longer horizons are more effective for module and system tasks, while short-horizon TTS remains competitive on operators.
Best-of-four (T/4) achieves 102.6% of long-horizon performance on operators, 96.9% on modules, and 77.3% on systems. Best-of-two (T/2) follows the same pattern.
Long-horizon optimization (T) wins 9 of 12 comparisons, including all four system comparisons.